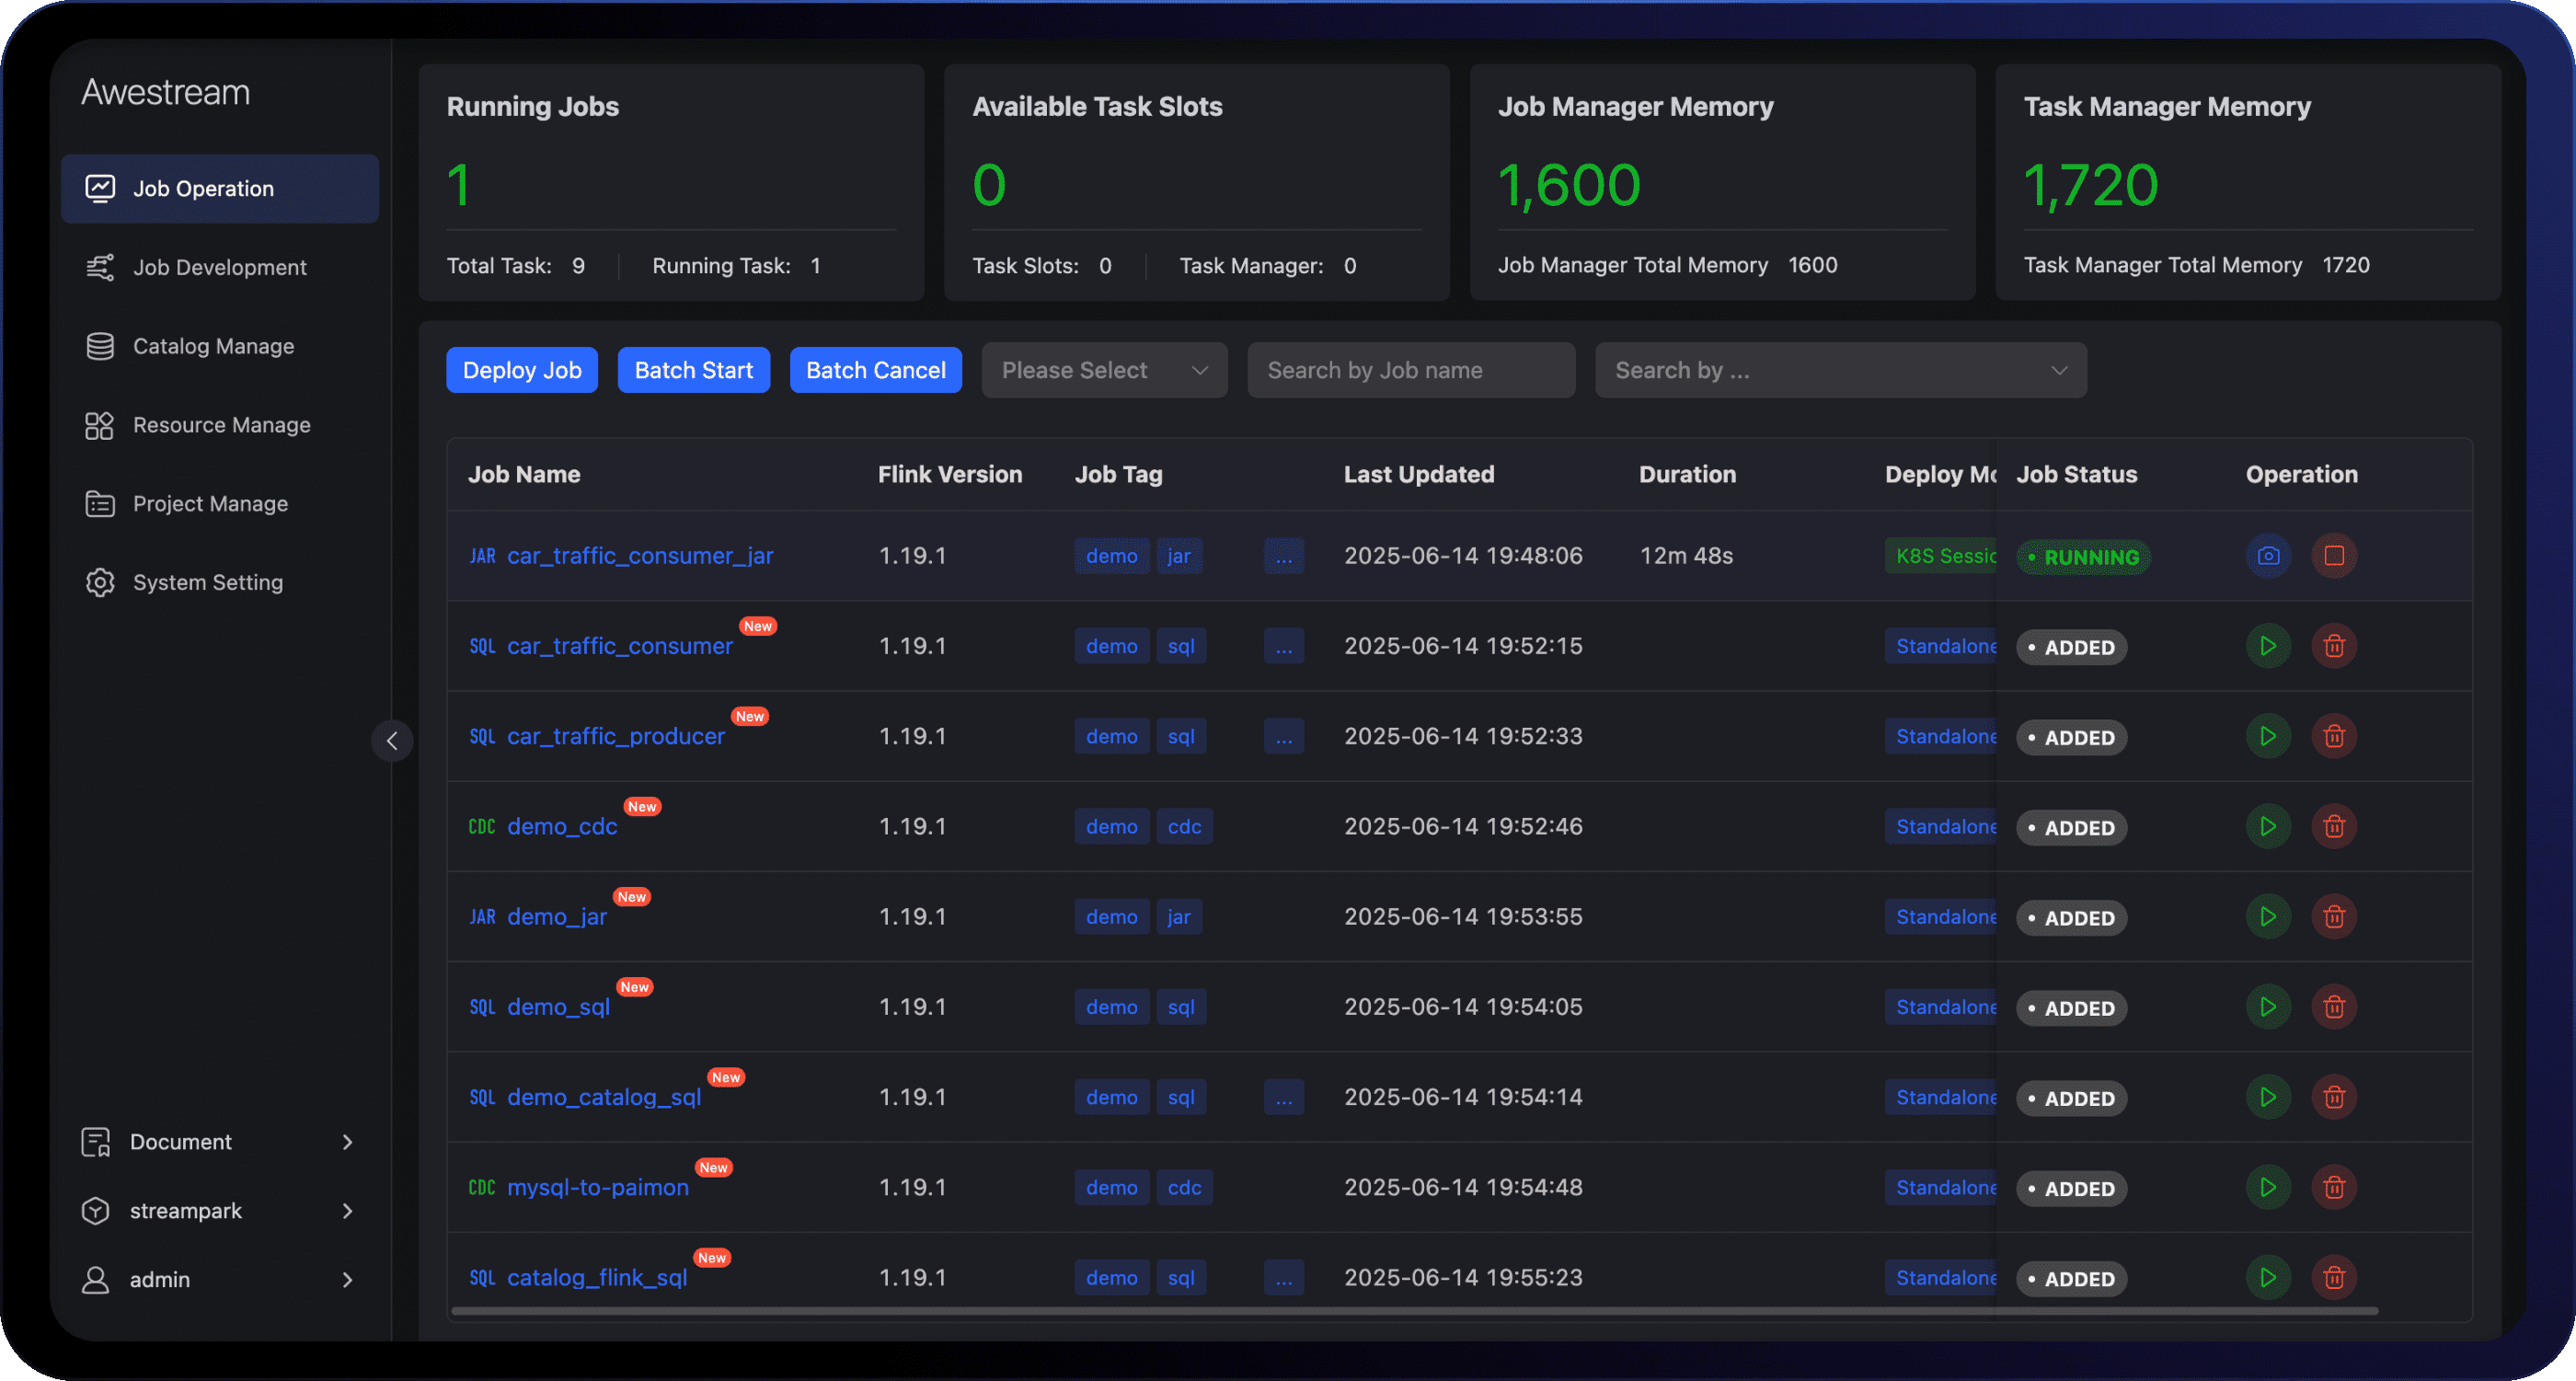
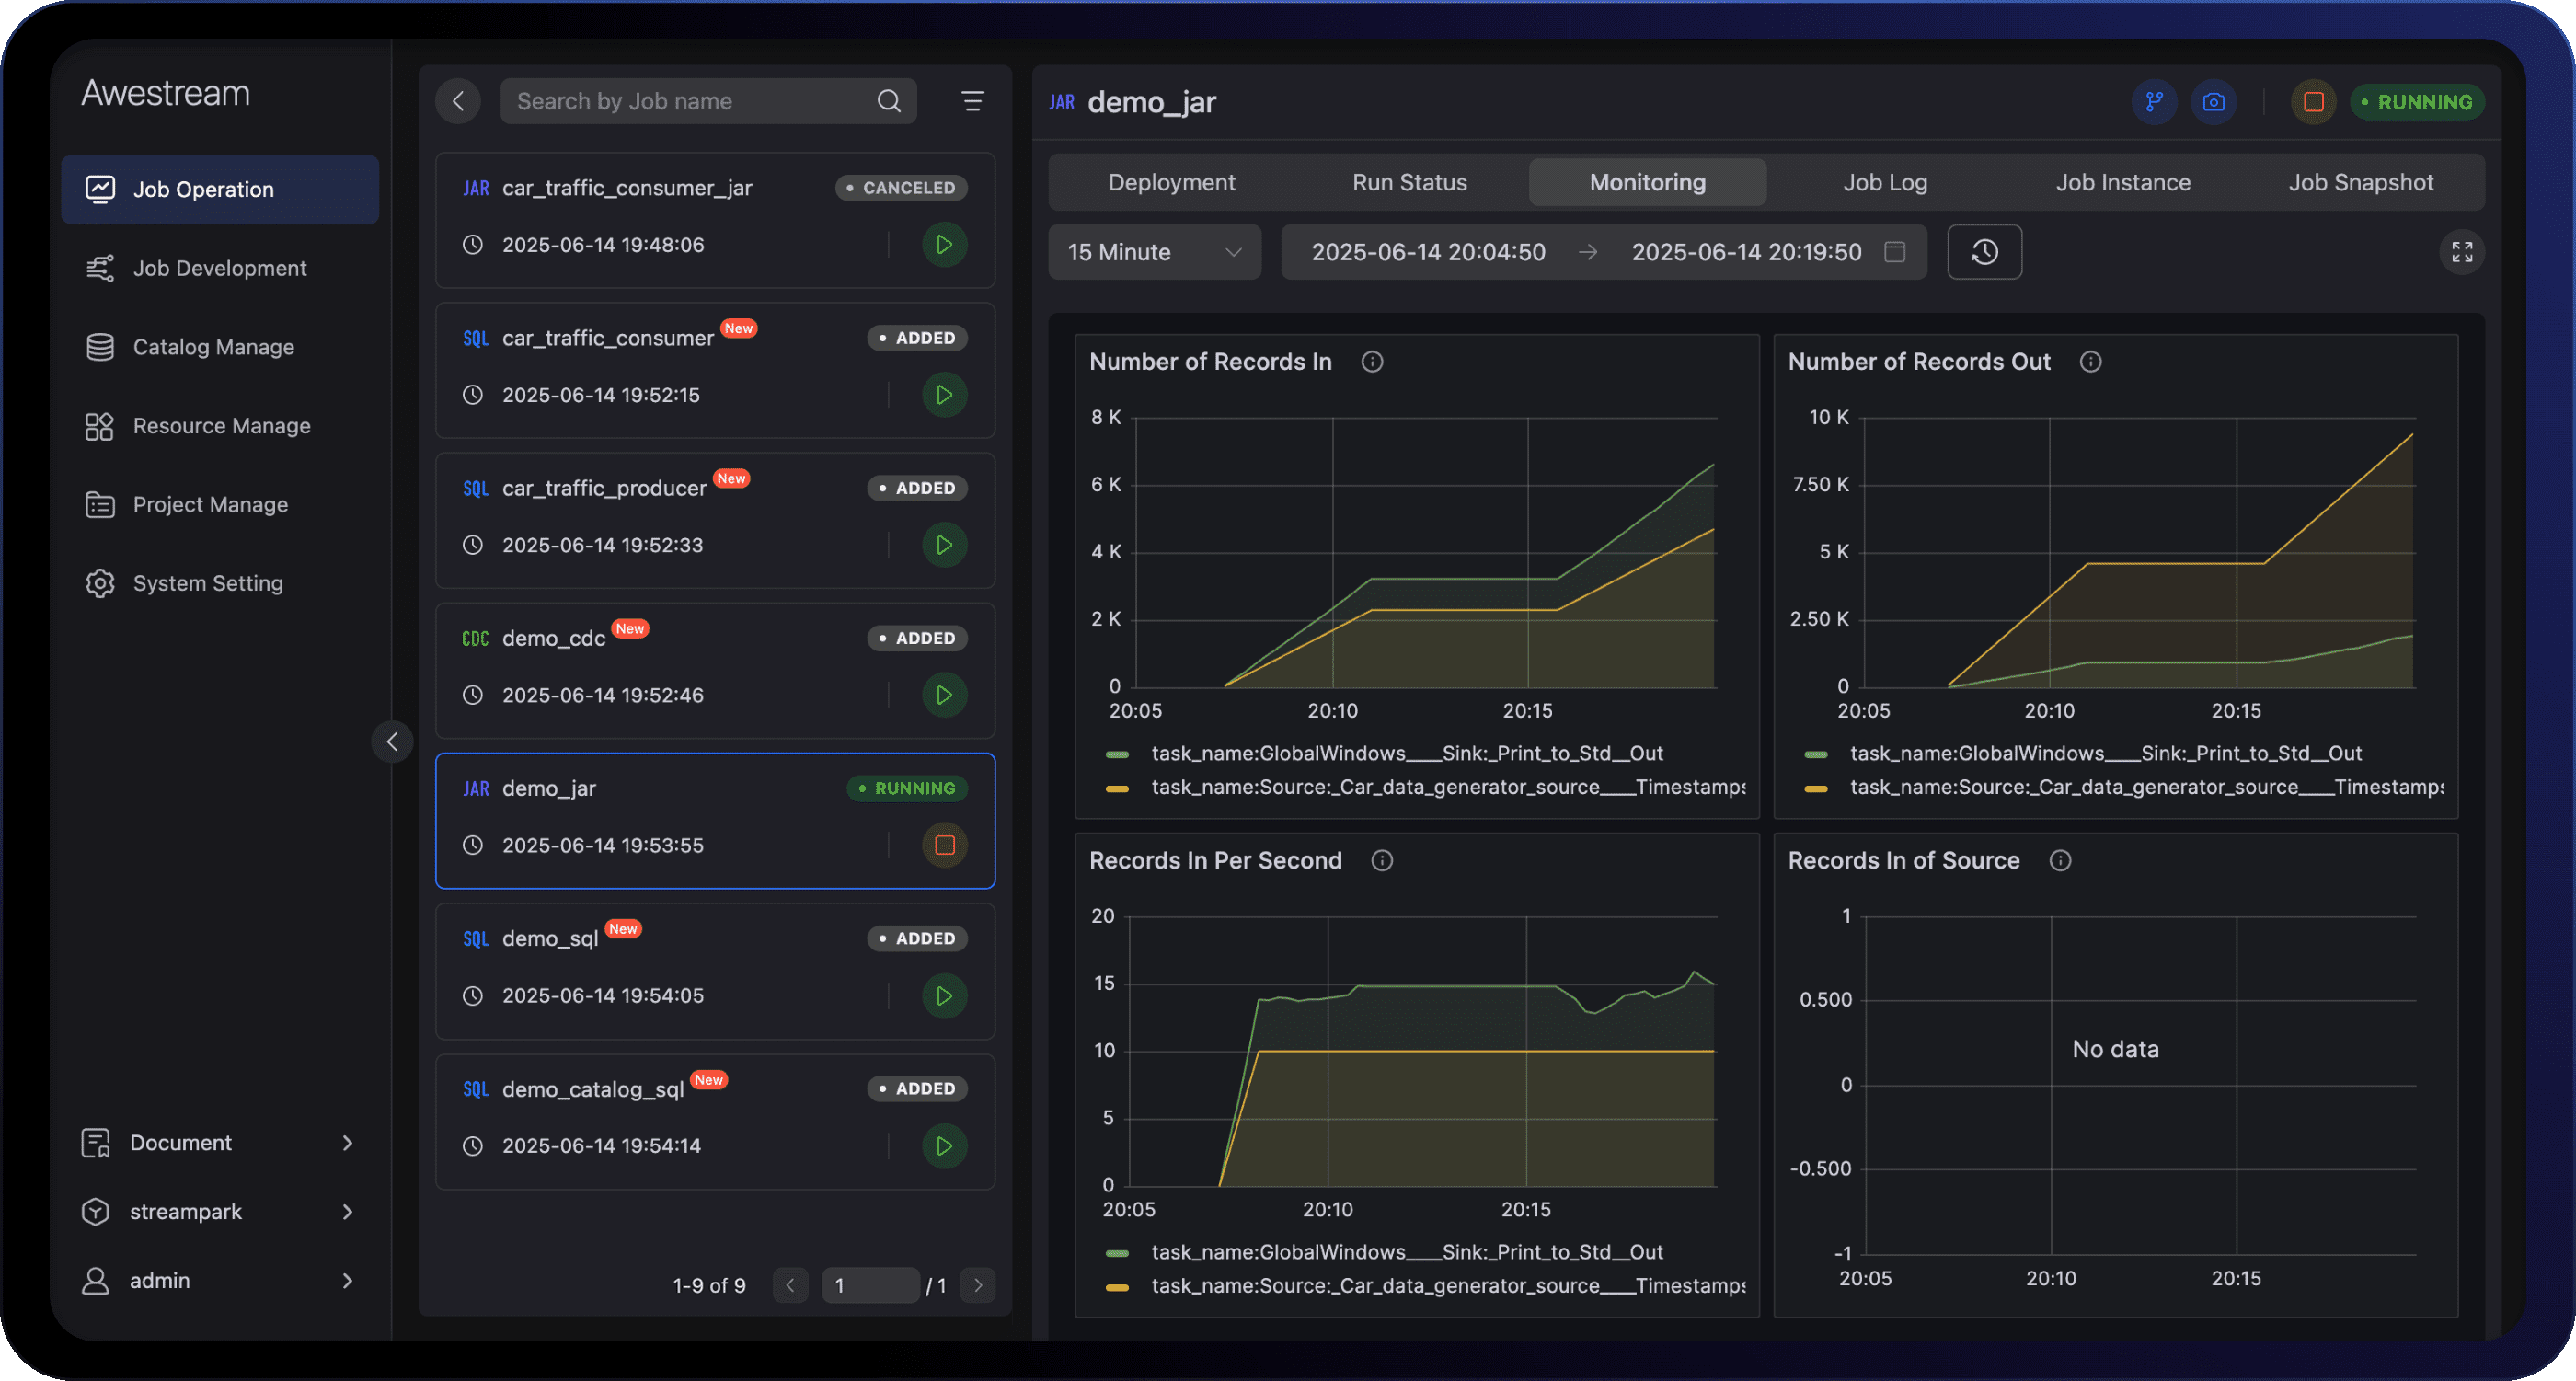
Time to value
Reach productionsooner.
Reuse catalog definitions and develop with AI, validation and data previews before publishing.
Shared context from draft to productionA one-stop AI-driven streaming lakehouse platform for data integration, development and operations across your infrastructure.
Built on Apache StreamPark. From its original creator.
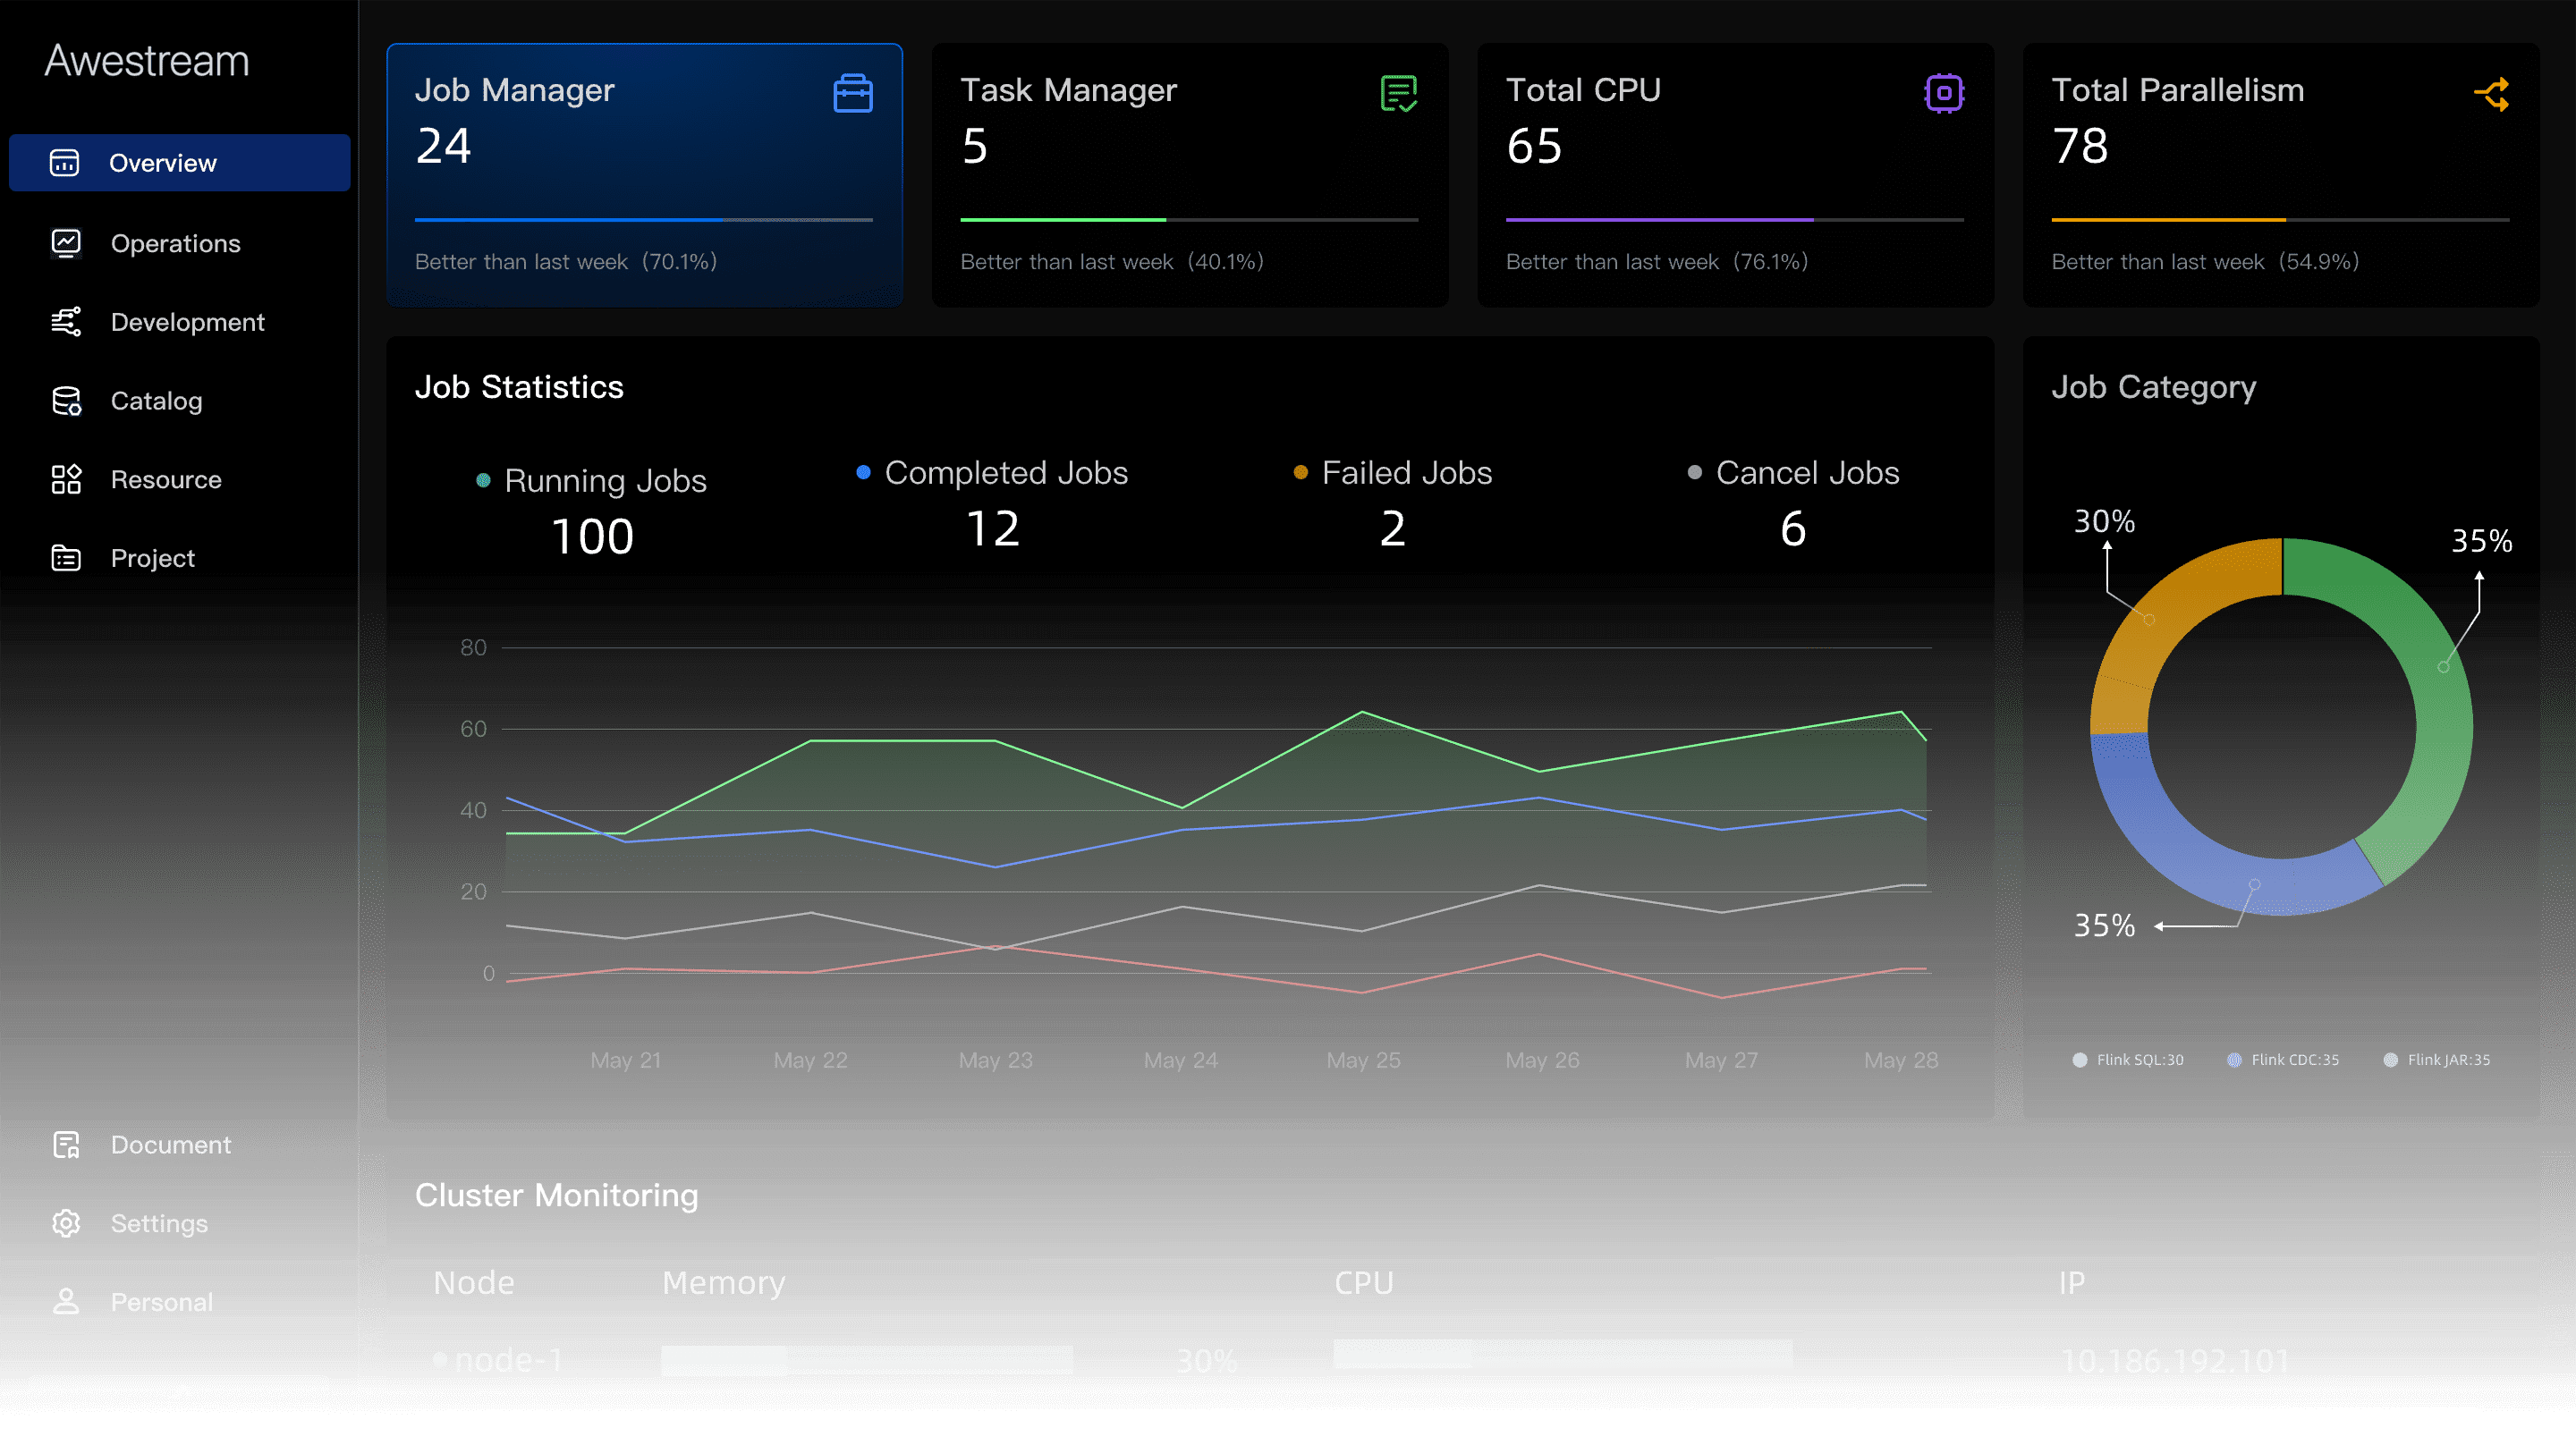


Connect ingestion, catalogs, AI-assisted development and operations so teams can turn changing data into usable tables and applications.
Reuse catalog definitions and develop with AI, validation and data previews before publishing.
Shared context from draft to productionManage pipelines, resources and runtime environments through a shared workspace.
One workspace for development and operationsKeep recovery, observability, access control, and audit in one lifecycle, backed by enterprise support.
Permissions, operational history and supportExplore your catalogs, write SQL and build CDC or ETL pipelines with AI assistance, validation and data previews.
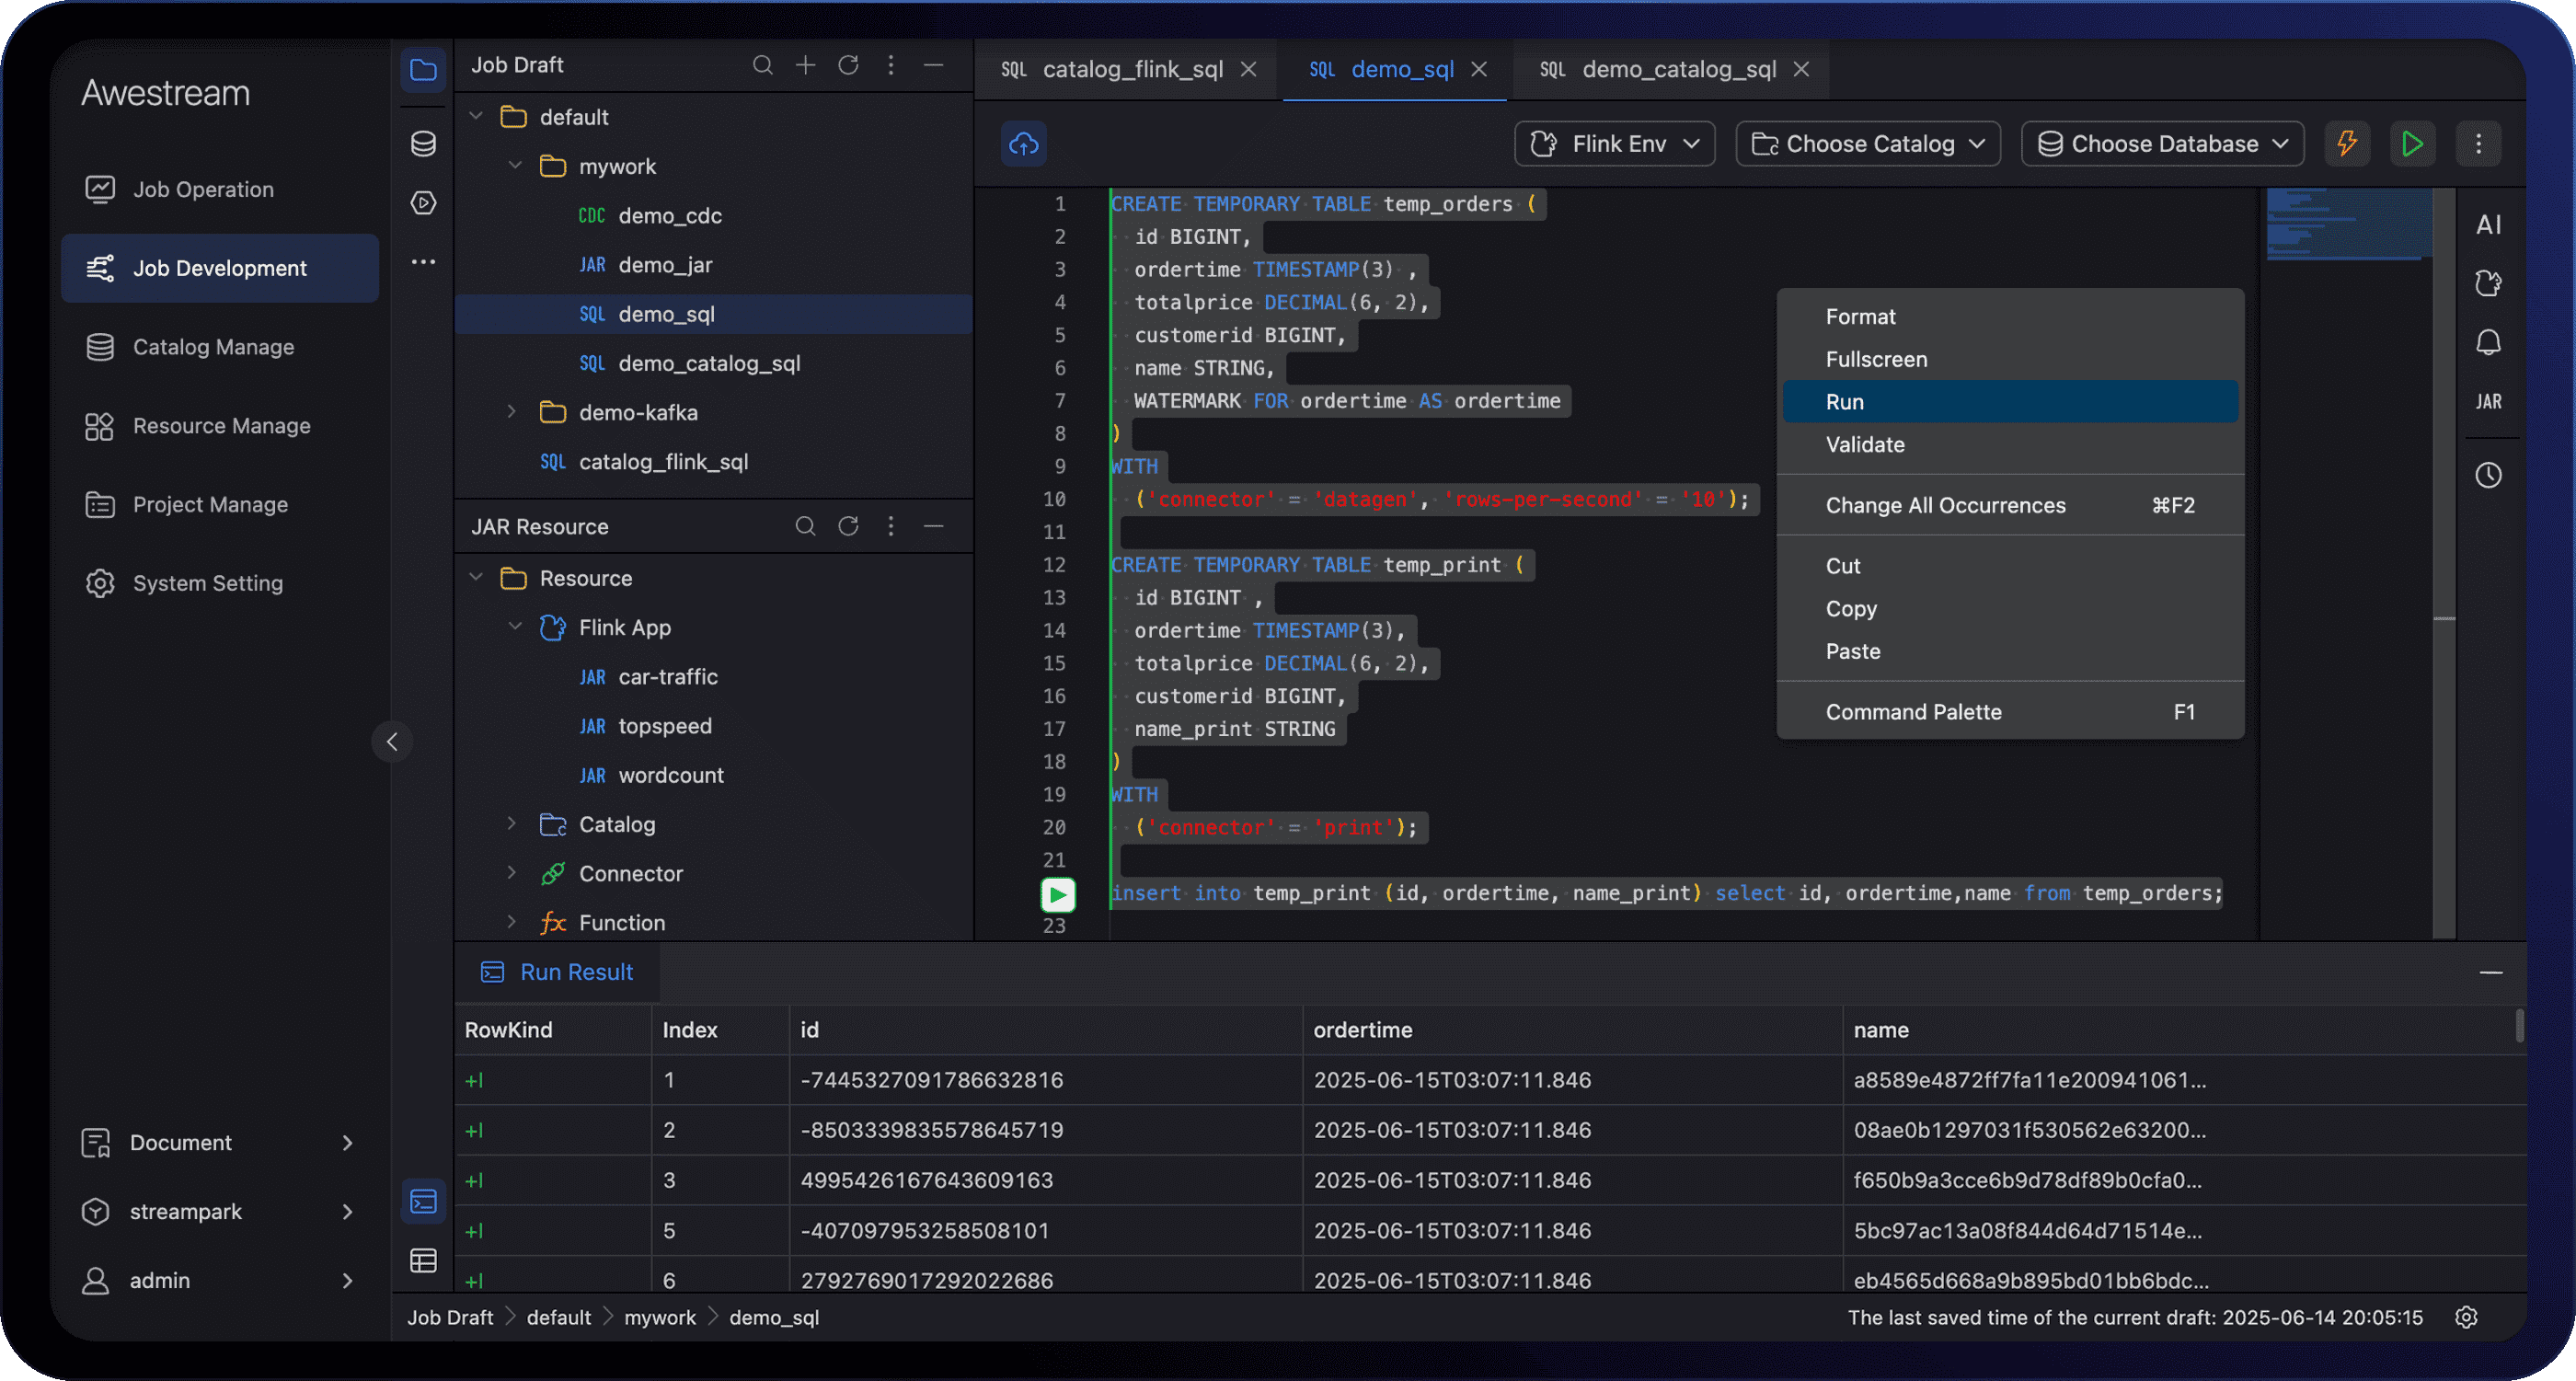
From source databases to lakehouse tables, manage full snapshots and continuous change streams in one platform.
Connect dozens of source types for real-time sync with Flink SQL and Flink CDC pipelines.
Build, validate and deploy pipelines in Realfuture, with filtering, transformations and field mapping.
Sync entire databases to your lakehouse, with configurable schema evolution for supported schema changes.
Develop with catalog context. Diagnose with runtime evidence.
Describe the logic you need. AI uses catalog schemas to draft Flink SQL and visual ETL flows, explain errors and suggest corrections in your editor.
Describe what to sync and where to send it. AI drafts Flink CDC YAML for selected tables or entire databases, with routing, filters and field mappings. Review the configuration, set schema evolution policies, then validate, deploy and monitor your pipeline in Realfuture.
Ask AI about a failing or slow job. It examines metrics, checkpoints, exceptions and logs to explain likely causes and suggest next steps for your team.
Bring catalogs, real-time data integration, AI-assisted development and operations into one platform.
Catalog context and AI connect sources to Flink and Flink CDC, then to lakehouse storage and analytics.
Enterprise enhancements bring shared catalogs, AI-assisted development and diagnosis, Flink CDC and lakehouse integrations into one platform.
Browse catalogs and manage tables and views. Reuse their metadata in SQL, CDC and ETL workflows.
Catalog & metadataDevelop, validate and run SQL, JAR, ETL and CDC workloads with shared connectors, dependencies and runtime settings.
Flink & Flink CDCUse schemas, job definitions and runtime evidence to support development and troubleshooting, with changes reviewed by your team.
Context-aware AIWork with Paimon lake tables, Fluss streaming storage, and Doris or StarRocks analytics through integrated catalogs and connectors.
Lakehouse & analyticsDeploy Realfuture once to manage Flink jobs across multiple YARN and Kubernetes clusters, spanning clouds and data centers.
Run jobs on AWS Kubernetes, Google Cloud Kubernetes and on-premises YARN from the same Realfuture platform.
Manage jobs on existing standalone Flink clusters alongside your YARN and Kubernetes deployments.
Choose from multiple Hadoop environments and YARN queues when deploying each Flink job.
Select a Kubernetes deployment target for each job, across cloud providers and data centers.
Use Flink for processing, Paimon for lake tables, Fluss for streaming storage, and Doris or StarRocks for analytics. Realfuture connects their workflows.
MySQL · PostgreSQL · Oracle · SQL Server · MongoDB · Apache Kafka · Apache Pulsar
Apache Flink · Apache Flink CDC · Flink SQL · Visual ETL · AI assistance · AI diagnosis
Apache Paimon · Apache Fluss · Apache Iceberg · Apache Doris · StarRocks · ClickHouse · Elasticsearch
Standalone · Hadoop YARN · Kubernetes · On premises · Private cloud · Public cloud · Hybrid cloud · BYOC
Bring a representative workload and your constraints. Leave with a target architecture, expected impact, and practical proof-of-concept plan.